So, you've built a scraper that works for 100 pages. Now you need to scrape 1,000,000. This is where most projects fail. Scaling web scraping isn't just about "running more code"; it's about infrastructure, error handling, and intelligent proxy management.
The 3 Pillars of Scalable Scraping
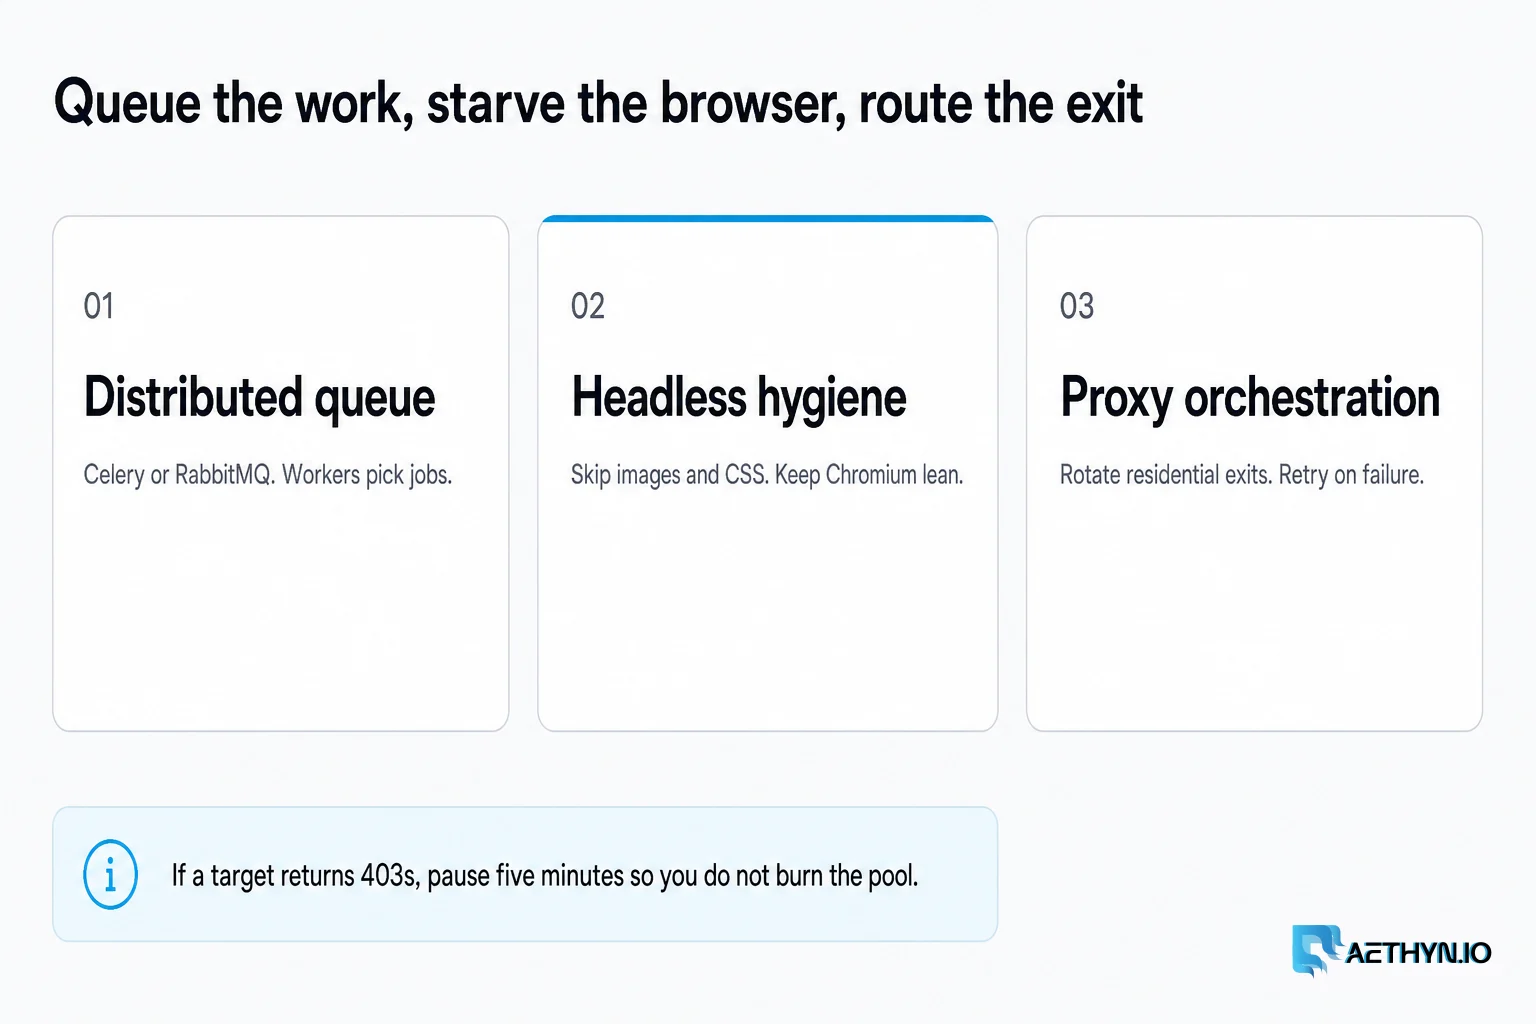
1. Distributed Architecture
Don't run everything on one server. Use a task queue (like Celery or RabbitMQ) and distribute the load across multiple worker nodes. This prevents your "master IP" from being flagged and spreads the CPU load.
2. Headless Browser Management
Tools like Playwright and Puppeteer are powerful but resource-heavy. At scale, you should:
- Disable Images/CSS: Don't waste bandwidth on visual elements you don't need.
- Use "Stealth" Plugins: Bypassing fingerprinting is easier when you look like a real Chrome user.
3. Intelligent Proxy Orchestration
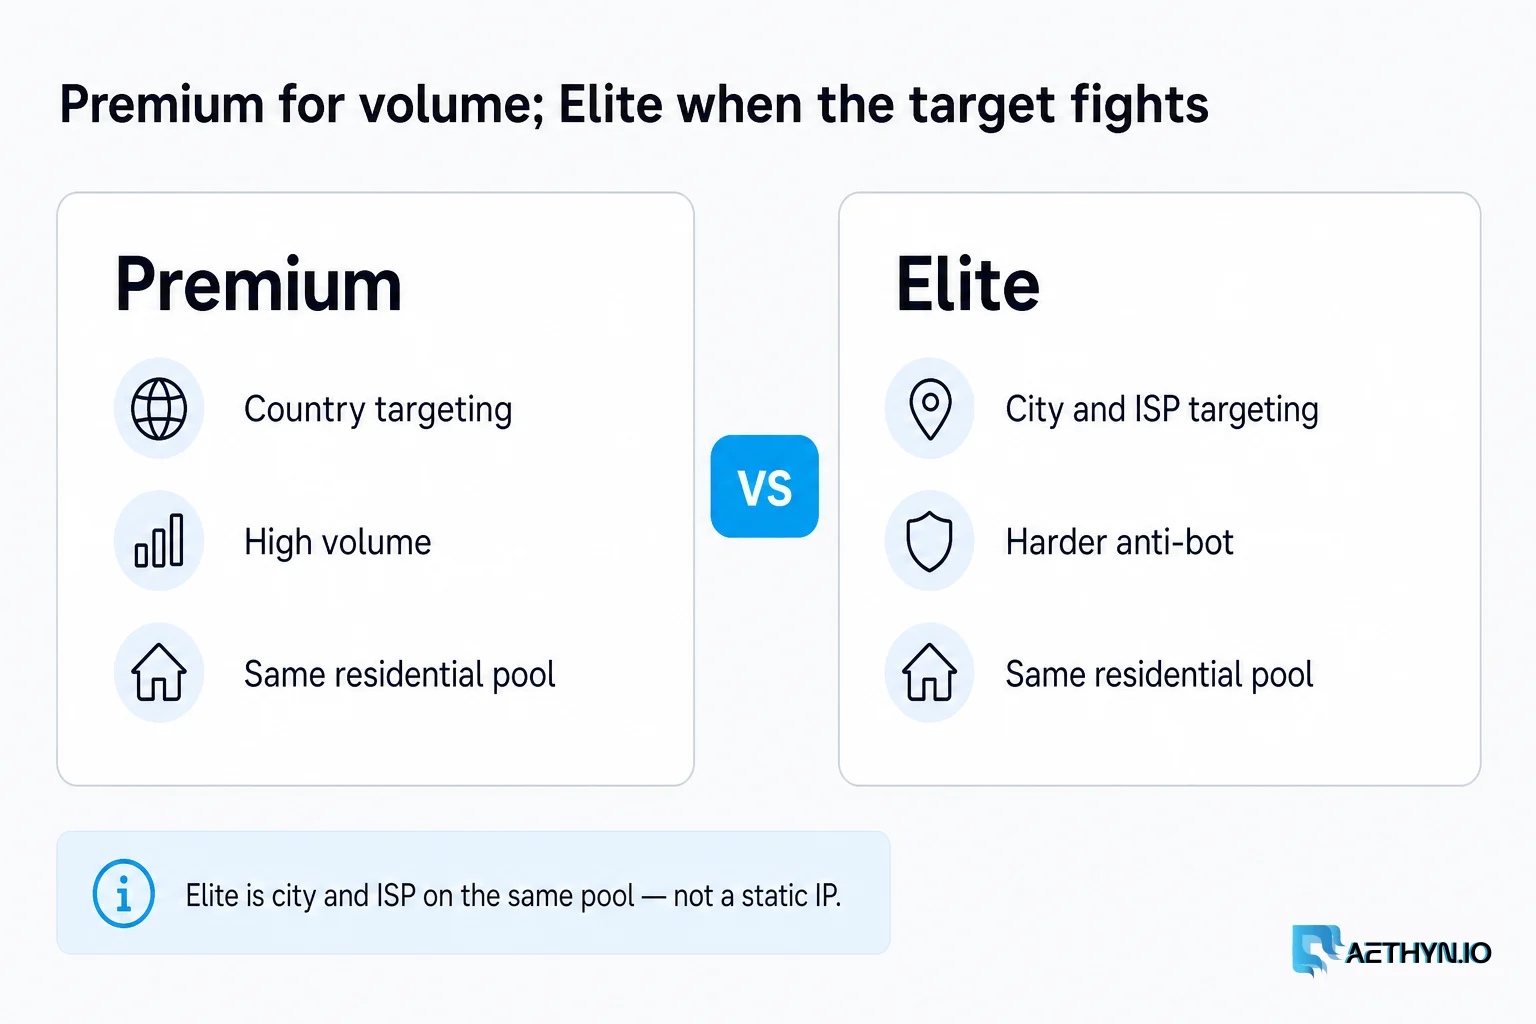
At 1,000,000 requests, you can't afford a 50% failure rate. Premium and Elite draw from the same residential pool — HTTP and SOCKS5 included. Sticky is a hold on a rotating-pool IP, not a dedicated address.
- Premium for volume: Country targeting for sites that don't fight.
- Elite when the target fights: City and ISP targeting plus harder anti-bot — not a static SKU.
[!TIP] Scaling Tip: Implement a "Circuit Breaker" pattern. If a specific target starts returning 403 errors consistently, stop scraping for 5 minutes to avoid burning through your proxy pool and bandwidth.
Cost Optimization at Scale
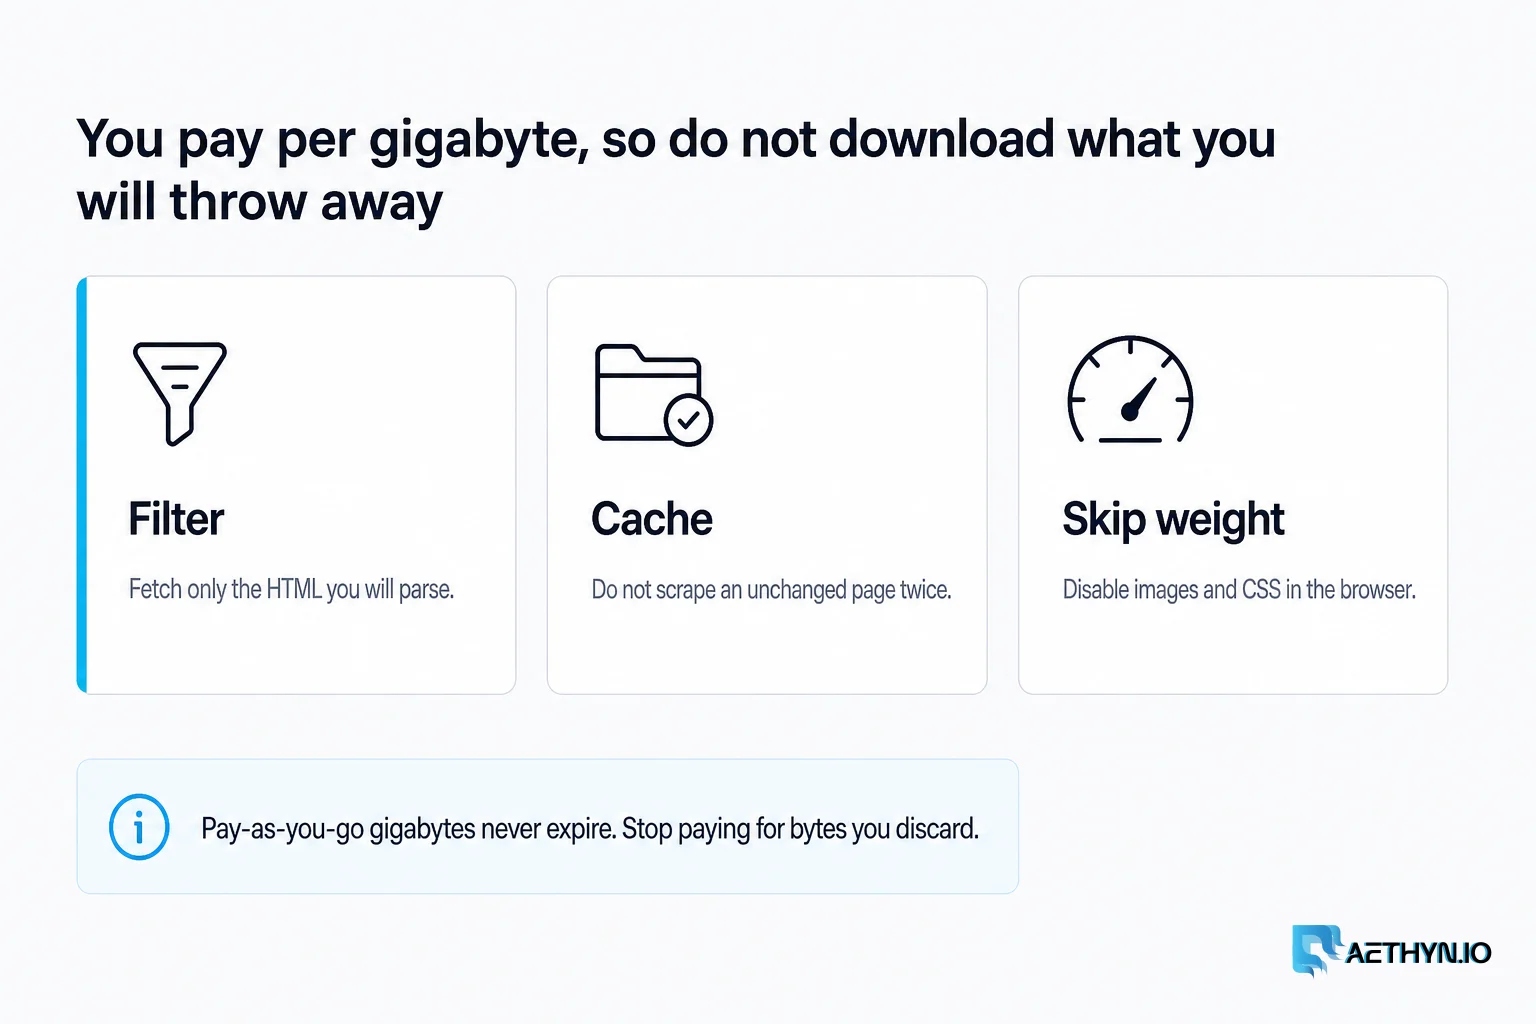
When you're scraping millions of pages, bandwidth costs add up. You pay per gigabyte, so do not download what you will throw away. See pricing — pay-as-you-go gigabytes never expire.
- Filter Your Requests: Use regex to only download the HTML you need.
- Cache Results: Don't scrape the same page twice if the data hasn't changed.
- Skip images and CSS: Headless browsers should not fetch assets you will discard.
Building a 1M Request Pipeline
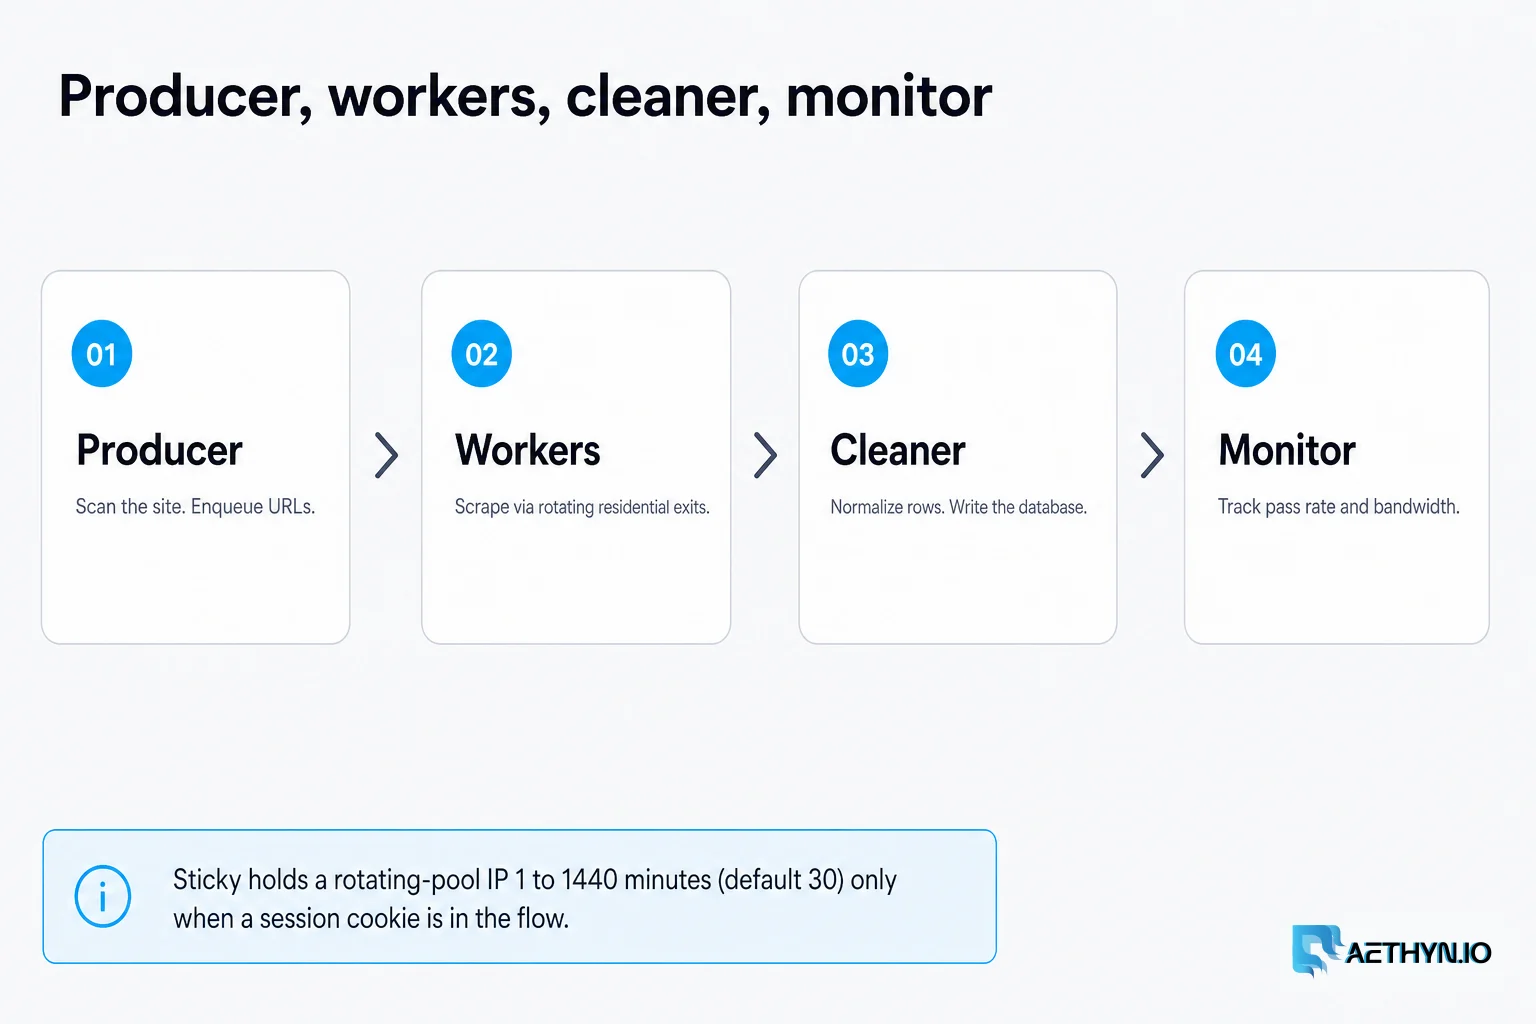
- Producer: Scans the site and adds URLs to a queue.
- Workers: Pick up URLs and scrape them using rotating residential exits. Use sticky only if a session cookie is in the flow (1–1440 minutes, default 30) — a hold on a rotating-pool IP, not a dedicated address.
- Cleaner: Normalizes the data and saves it to your database.
- Monitor: Tracks success rates and bandwidth in real-time.
Ready to Scale?
Aethyn was built for high-throughput applications. Premium handles bulk pipelines; Elite clears targets that reject commodity residential. Whether you're doing 1k or 1M requests, our network scales with you.
Guides, integrations & docs
Continue reading
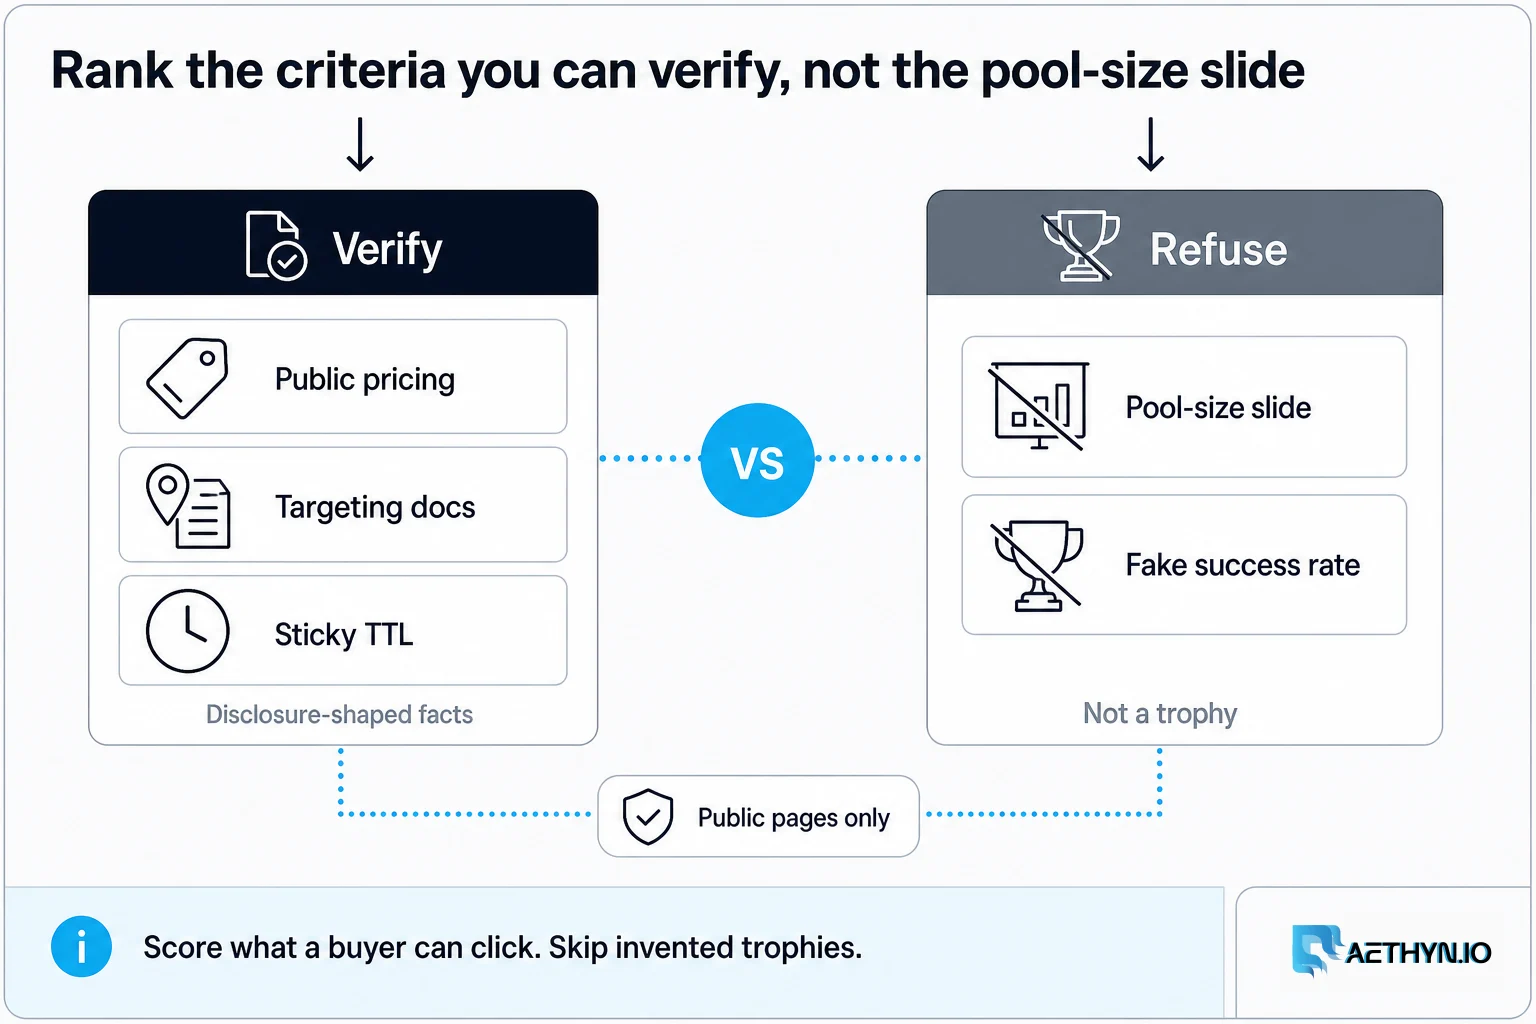
Best Residential Proxy Providers in 2026
Nine residential proxy providers compared on published price, targeting, and self-serve signup. A short list if you want to buy residential proxies in 2026.
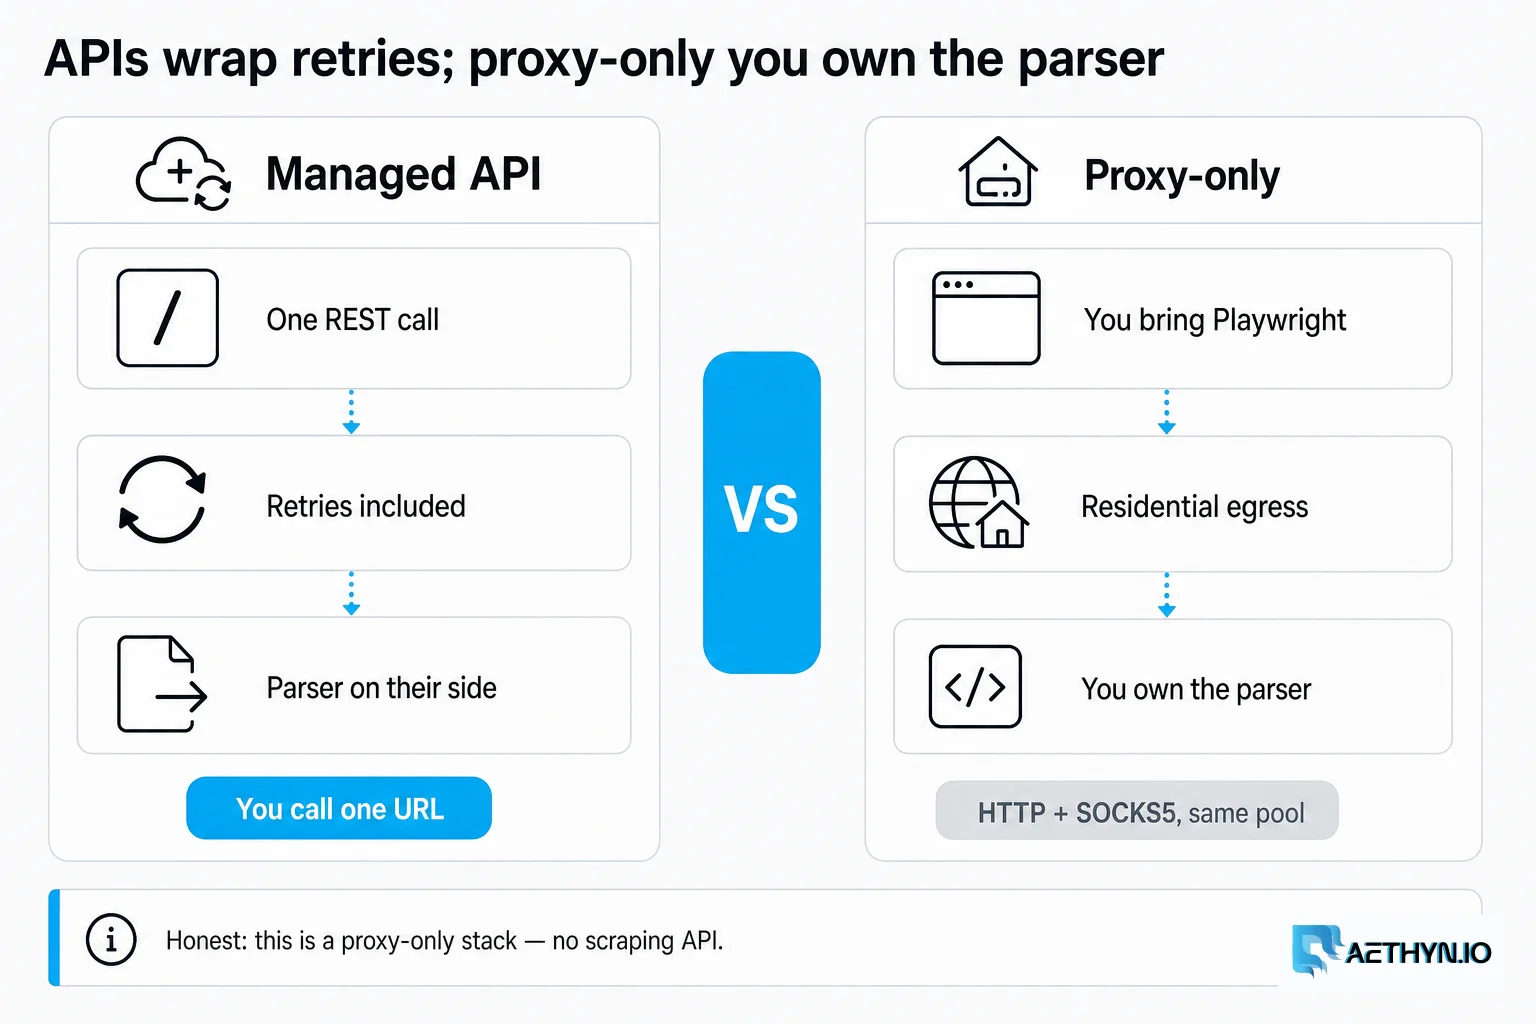
ScraperAPI vs Proxy-Only: Web Scraping API Comparison (2026)
ScraperAPI and ZenRows bundle proxies with rendering and retries. Aethyn and Bright Data sell raw proxies. We compare cost, control, and maintenance for engineering teams in 2026.
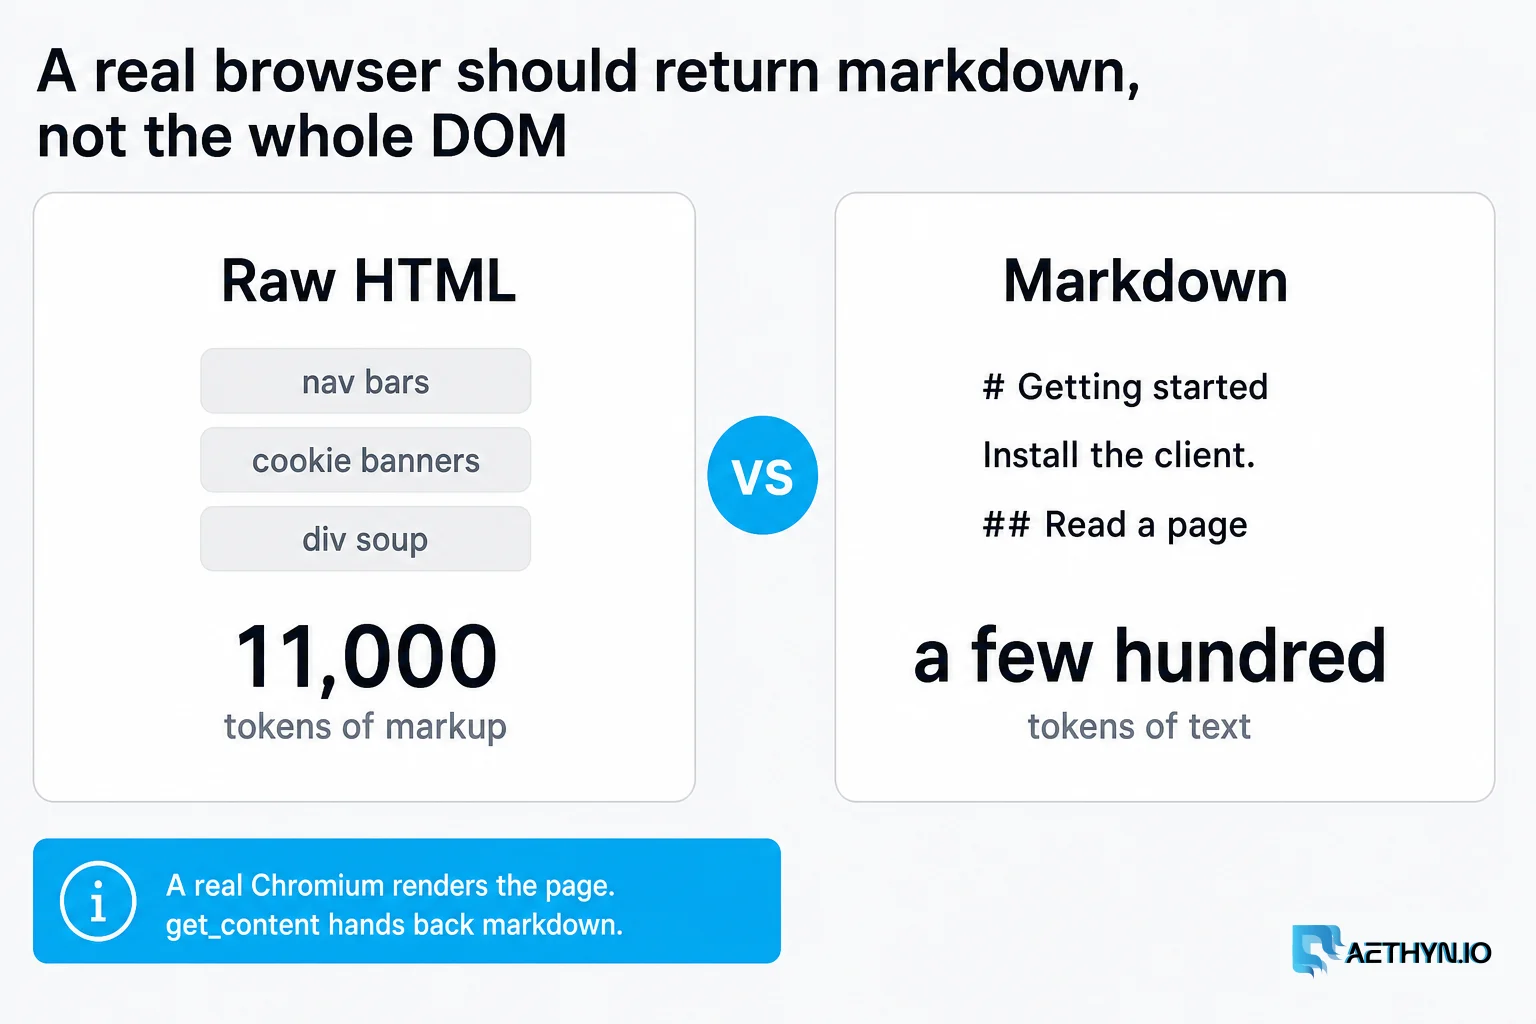
Give Your AI Agent a Real Browser (That Doesn't Eat Your Context Window)
Built-in fetch chokes on JavaScript sites and raw-HTML browser tools flood your context with DOM soup and screenshots. Here's an MCP that renders real pages, returns clean markdown, and routes through residential IPs — one npx command.
Premium or Elite residential proxies
Join developers scaling scraping and automation with Aethyn Premium and Elite pools from €2.00/GB.