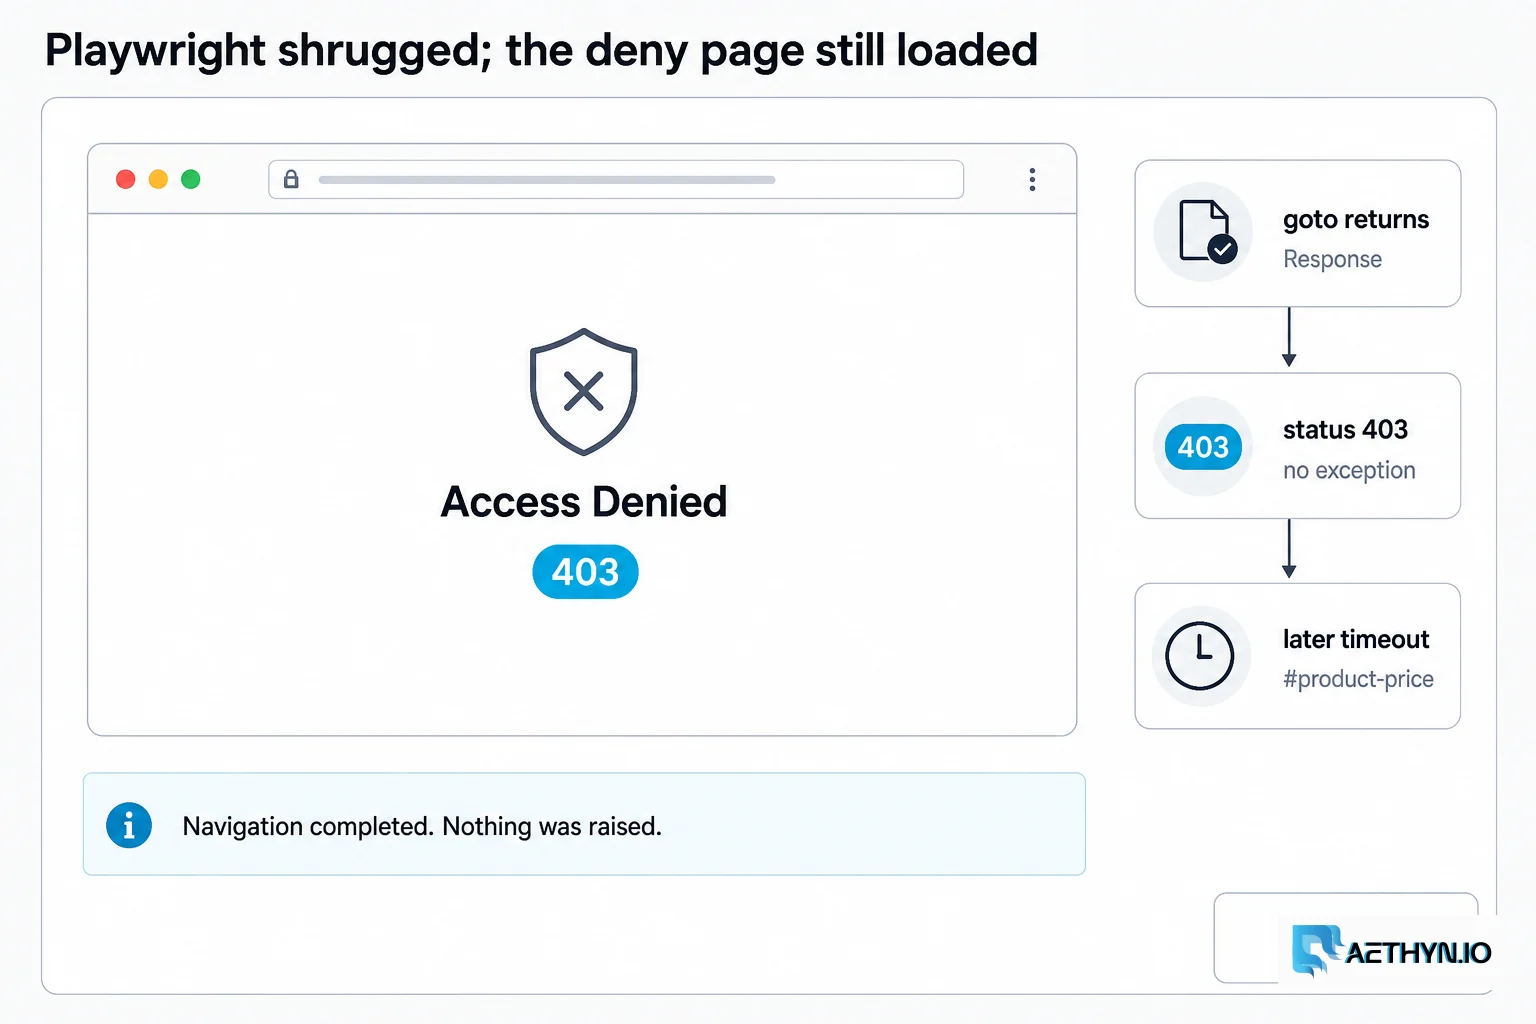
The anti-bot page loaded. Playwright shrugged. page.goto handed back a Response with .status 403 and raised nothing. Your next exception was a timeout waiting for #product-price — minutes of confusion later. Selenium’s driver.get is quieter still: no exception, driver.title becomes Access Denied.
This is the Class-3 error-string problem: the library never framed the event as a block. Full pipeline: Your scraper framework did not tell you it was blocked.
Why engineers search the wrong string
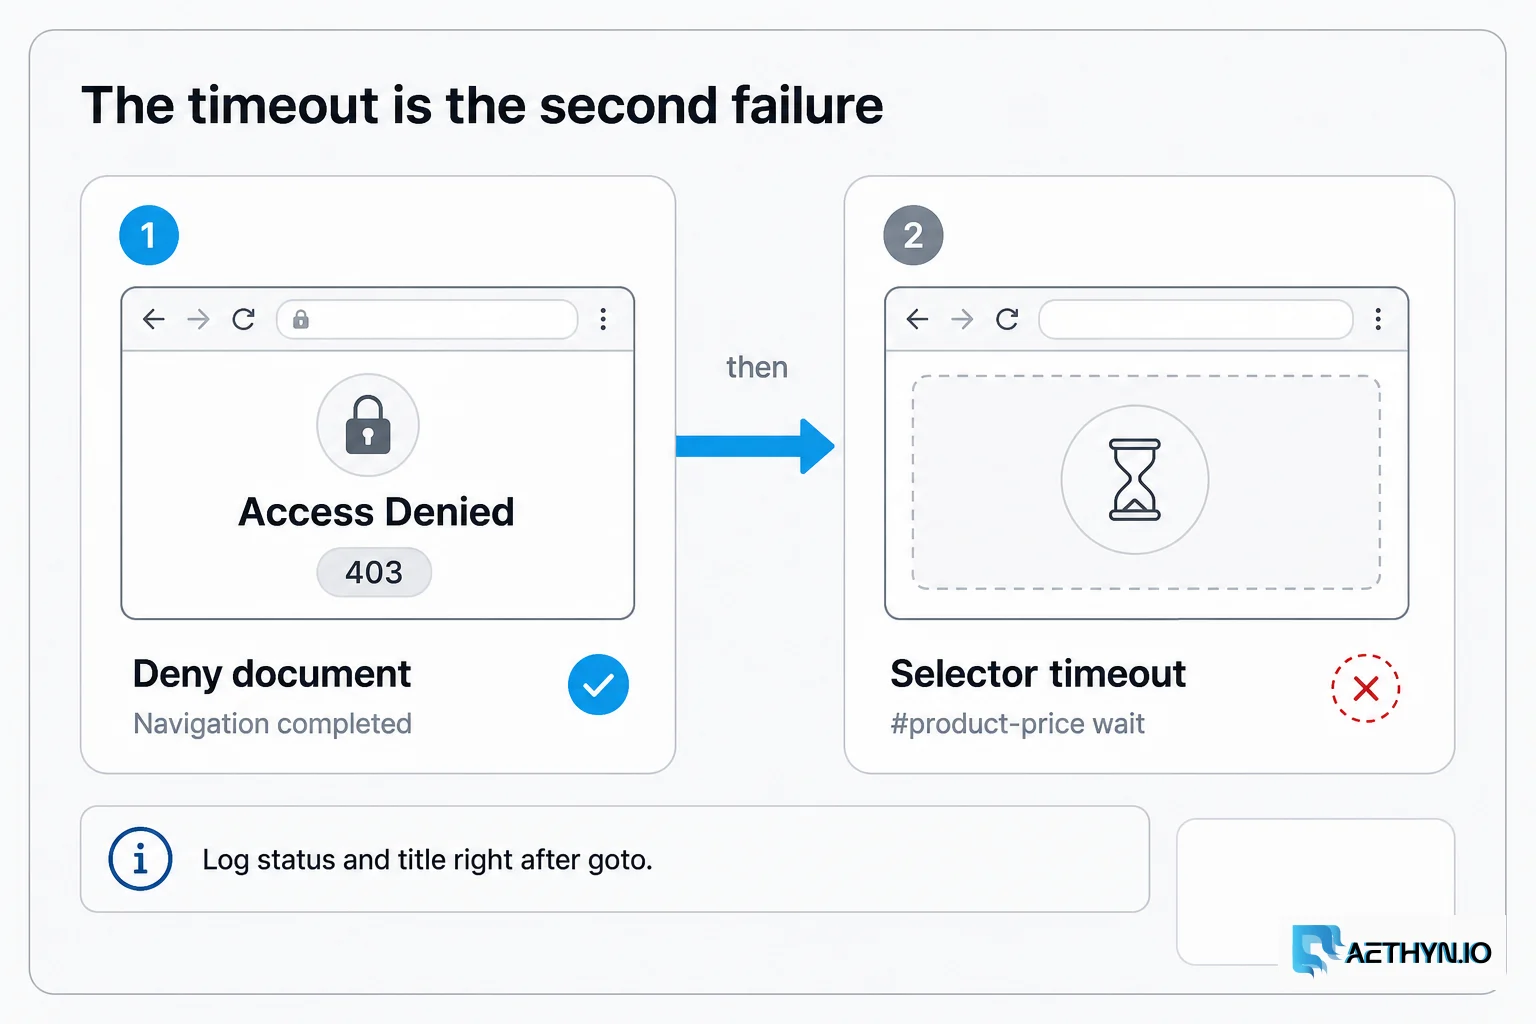
Incident chats fill with Timeout 2500ms exceeded / waiting for locator("#product-price") / empty Selenium TimeoutException messages. Those strings describe the second failure. The first failure was a deny document that completed navigation successfully. Until you log response.status and page.title() immediately after goto, every anti-bot vendor looks like a flaky selector.
That is why this post exists beside the vendor guides: Akamai, DataDome, and Kasada each have distinct receipts — but none of them matter if your framework never surfaces the HTTP event.
Verified behaviour (automation stacks)
| Stack | On HTTP 403 HTML block |
|---|---|
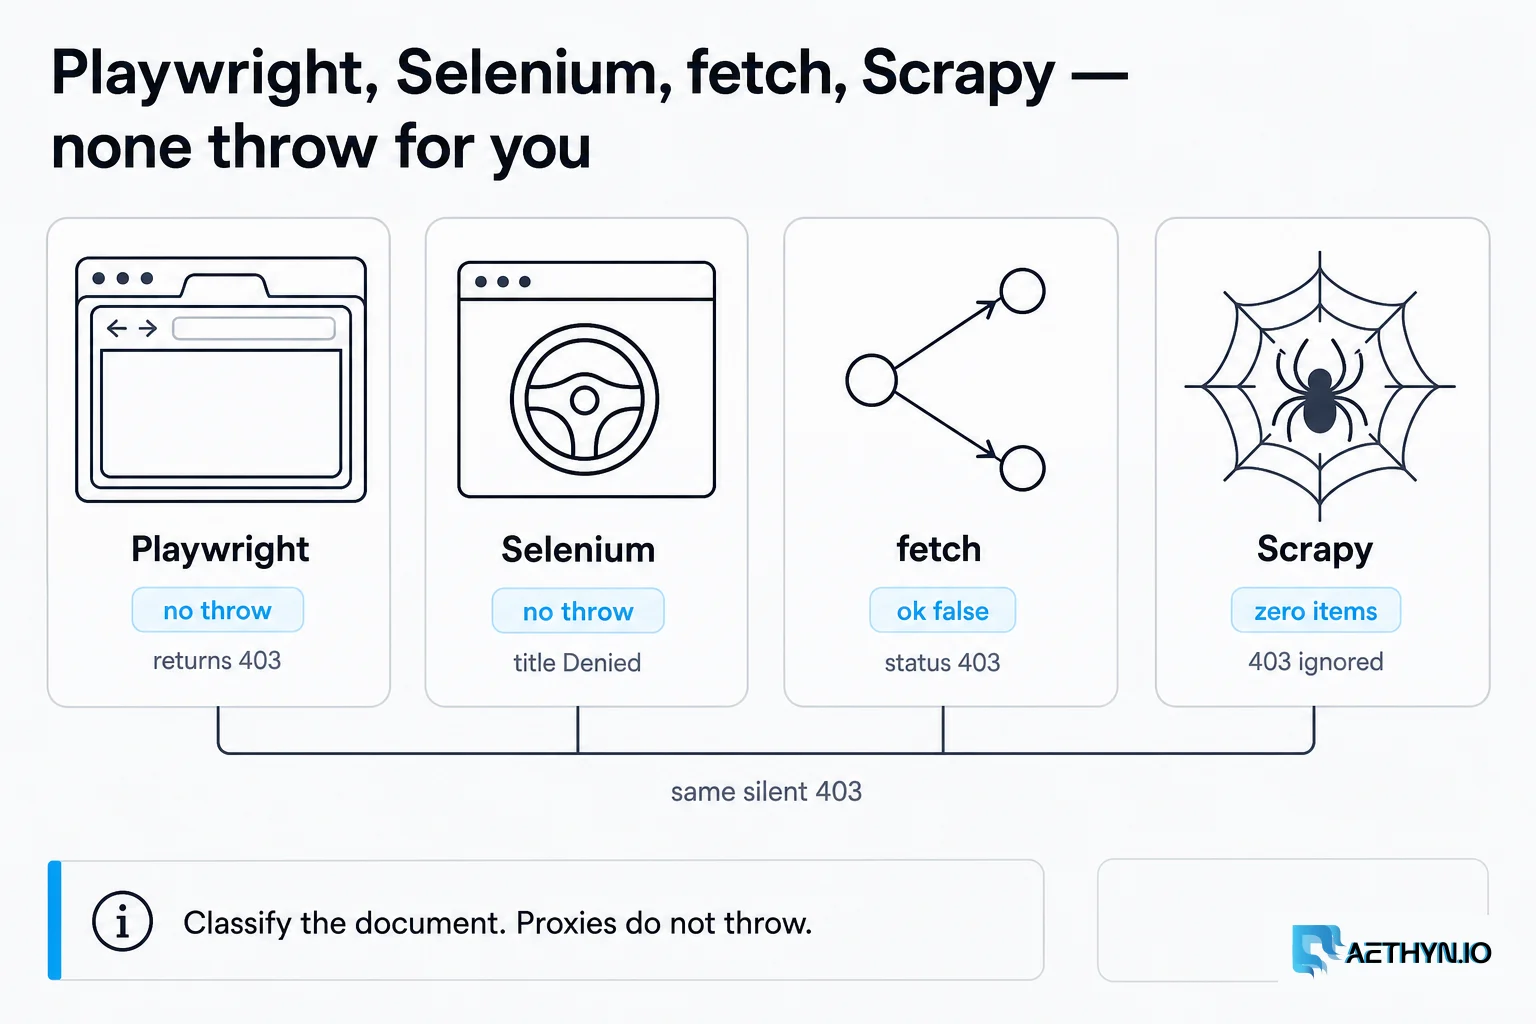
| Playwright | goto returns Response; no throw; later selector timeout |
| Selenium | get no throw; title may be Access Denied |
Node fetch | ok=false, status 403 — no throw |
| Scrapy (default) | Often logs and ignores 403 → “zero items” |
Soft sibling: HTTP 200 Access Denied bodies also look “successful” to transport-level checks.
Scrapy’s default handling deserves a callout: many spiders log Ignoring response <403 …>: HTTP status code is not handled or not allowed and produce zero items with no exception in your parse callback. Enable explicit errbacks or handle 403 in the spider — silence is not success there either.
Classify before you wait
Code Snippetfrom playwright.sync_api import sync_playwright

def goto_classified(page, url: str):
    resp = page.goto(url, wait_until="domcontentloaded", timeout=45_000)
    status = resp.status if resp else None
    title = page.title()
    if status is not None and status >= 400:
        raise RuntimeError(f"blocked_or_error status={status} title={title!r}")
    if "access denied" in (title or "").lower():
        raise RuntimeError(f"blocked_document title={title!r}")
    return {"status": status, "title": title, "url": page.url}
Only after classification says the document is real should you call wait_for_selector on commerce nodes. Selector timeouts are symptoms, not diagnoses.
Selenium sketch of the same idea:
Code Snippetfrom selenium import webdriver

def get_classified(driver, url: str):
    driver.get(url)  # raises nothing on HTTP 403 HTML
    title = driver.title or ""
    if "access denied" in title.lower() or "just a moment" in title.lower():
        raise RuntimeError(f"blocked_document title={title!r}")
    return title
Proxy 407 hang ≠ site block
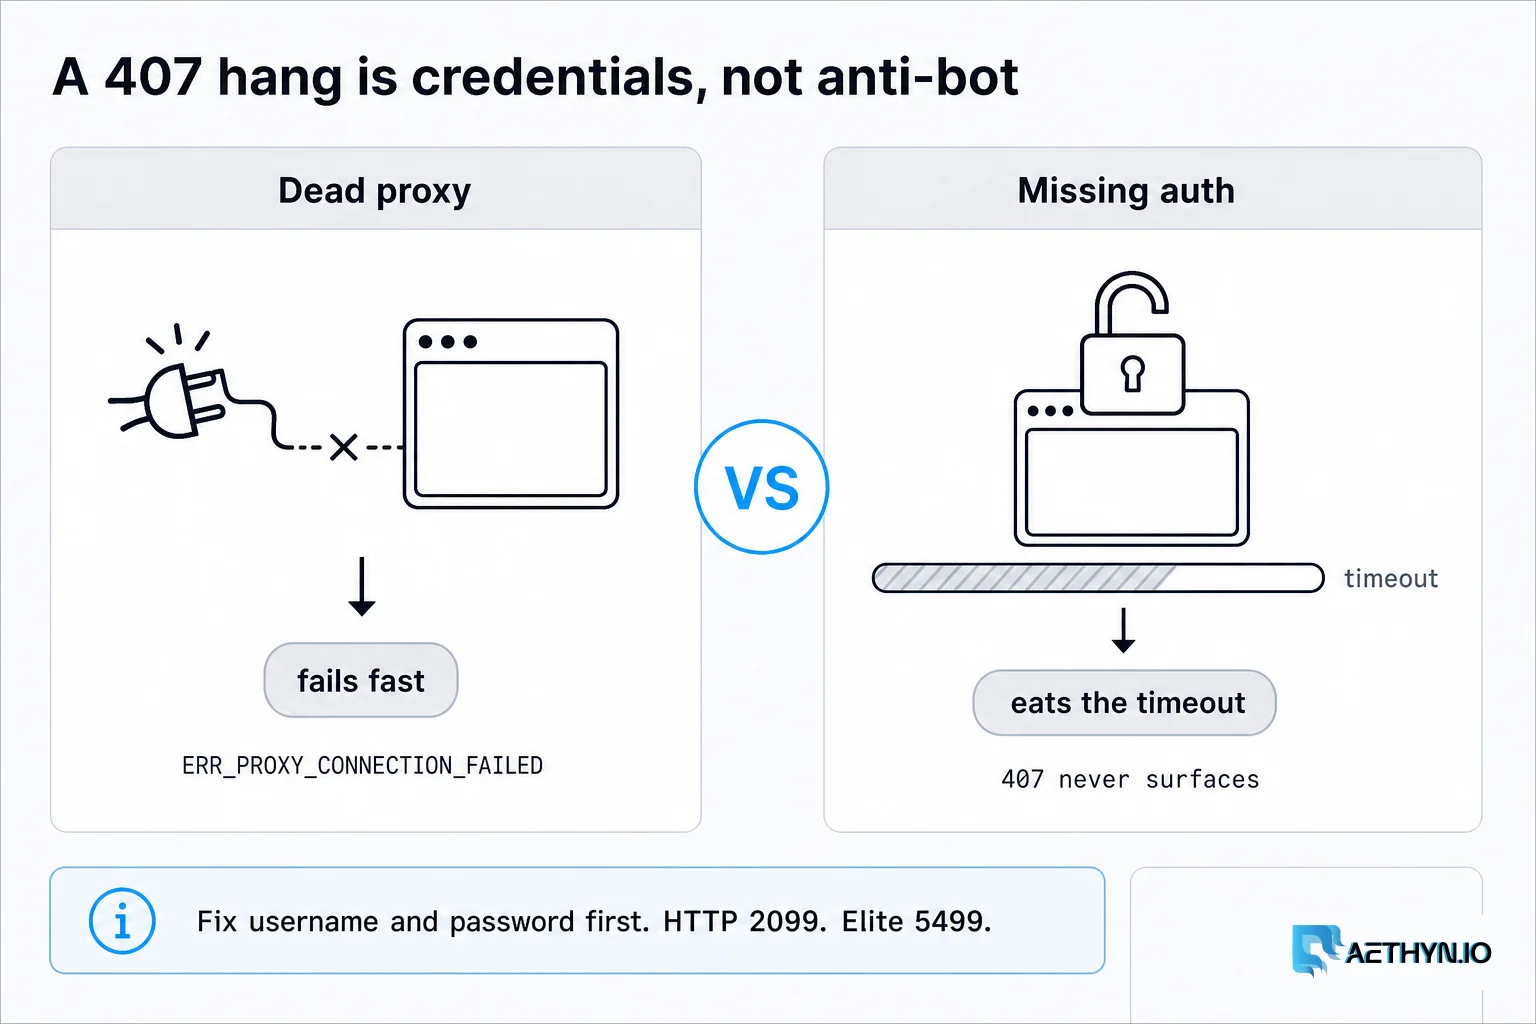
Misconfigured Playwright proxy auth against a 407 can hang until the full goto timeout with no 407 string — observed as a long TimeoutError. A dead proxy typically fails fast with net::ERR_PROXY_CONNECTION_FAILED. Configure username/password first:
- Premium HTTP 2099 / SOCKS5 1099
- Elite HTTP 5499 / SOCKS5 3499
Example proxy server for Playwright: http://aethyn-XXXXX-country-us-session-pw1-lifetime-30:PASSWORD@proxy.aethyn.io:2099 — see Playwright integration. Prefer Elite HTTP 5499 once attribution confirms Bot Management–class targets; keep Premium for routine A/B after classification.
Three-way curl outside the browser
When the browser is silent, confirm the wire:
Code SnippetURL=https://TARGET/
UA='Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/128.0.0.0 Safari/537.36'
curl -sS -o /dev/null -w 'plain %{http_code}\n' "$URL"
curl -sS -o /dev/null -w 'ua %{http_code}\n' -A "$UA" "$URL"
curl -sS -o /dev/null -w 'res %{http_code}\n' -A "$UA" \
  -x 'http://aethyn-XXXXX-country-us:PASSWORD@proxy.aethyn.io:2099' "$URL"
Then attribute with Identify which anti-bot blocked you — Akamai Reference strings, x-datadome: protected, Kasada UUID paths, and friends. Do not invent a bypass from a TimeoutError message.
Pipeline stages (memorize this order)
- Navigate — capture Response/status (Playwright) or title/URL (Selenium); never assume throw-on-deny
- Classify — block vs real document vs network/proxy failure
- Assert — commerce selectors only after classification says the HTML is real
- Attribute — send status, cookies, body prefix to the anti-bot hub
- Remediate — one change: IP tier or client stack — not both at once in a panic
Blind except Exception: retry loops violate stage 5 and burn Elite exits on fingerprint failures.
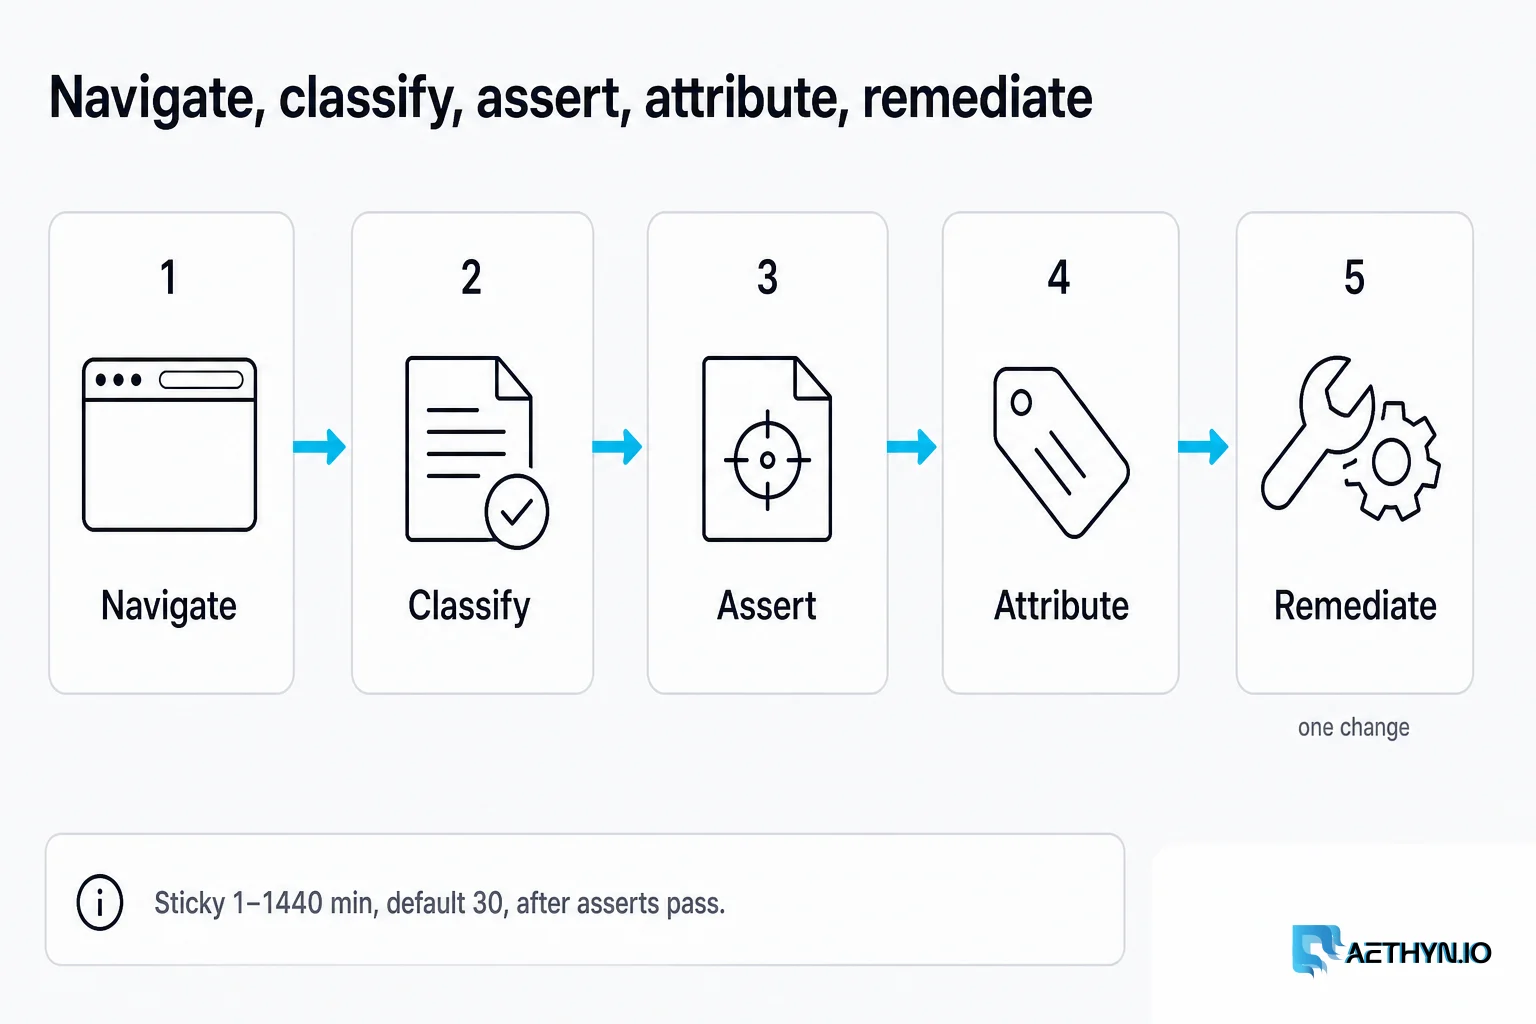
Remediate once
| Attribute result | Move |
|---|---|
| IP / reputation shaped | Premium or Elite residential |
| Fingerprint / JS challenge | Browser-grade stack + sticky exit after asserts pass |
| Soft 200 deny shell | Content gate first — 200 block page guide |
| Proxy auth hang | Fix credentials / ports before touching anti-bot settings |
Public-data scope only — this page does not teach CAPTCHA solving. Pair with sibling error posts when the classified document names a vendor: DataDome 403, Akamai Reference #18, Kasada 429.
Continue with the navigate → classify → assert → attribute → remediate stages: Framework silent blocks.
Common questions about this article
Does Playwright throw when a site returns HTTP 403?
Does Selenium raise on an Access Denied page?
Why did Playwright hang ~30s with a proxy?
Where do residential proxies fit?
Guides, integrations & docs
Continue reading
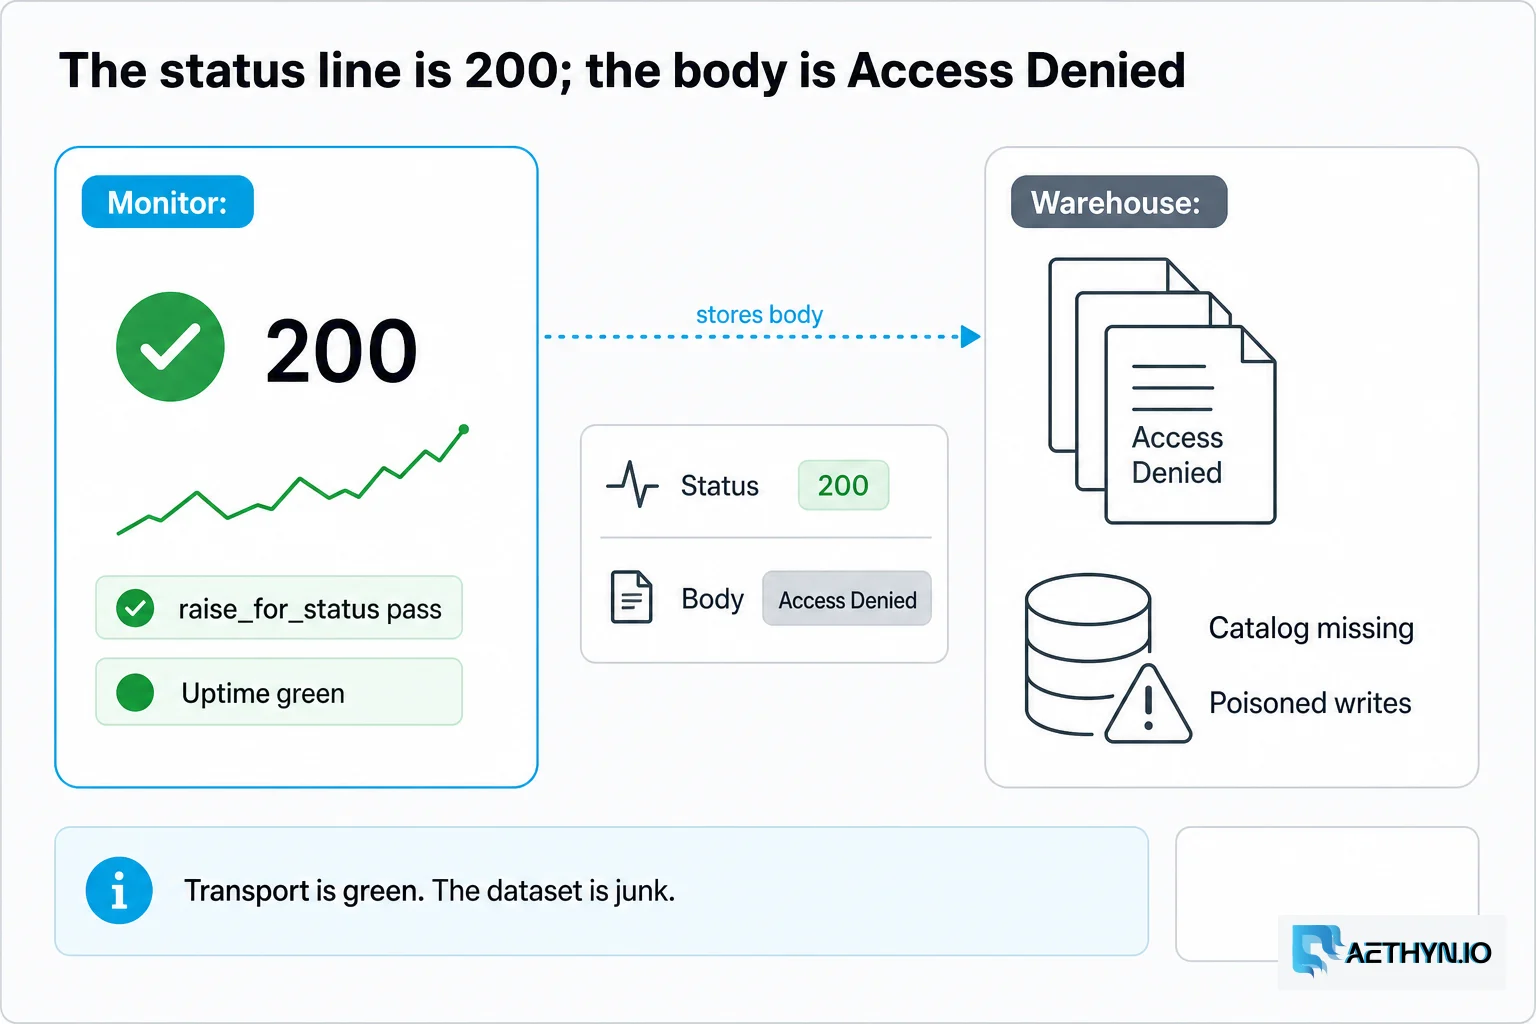
HTTP 200 Access Denied: Soft Blocks That Poison Scrapers
Status 200 can still be Access Denied or an AkamaiNetStorage unavailable page. Build title and content asserts so soft blocks stop looking like successful scrapes.
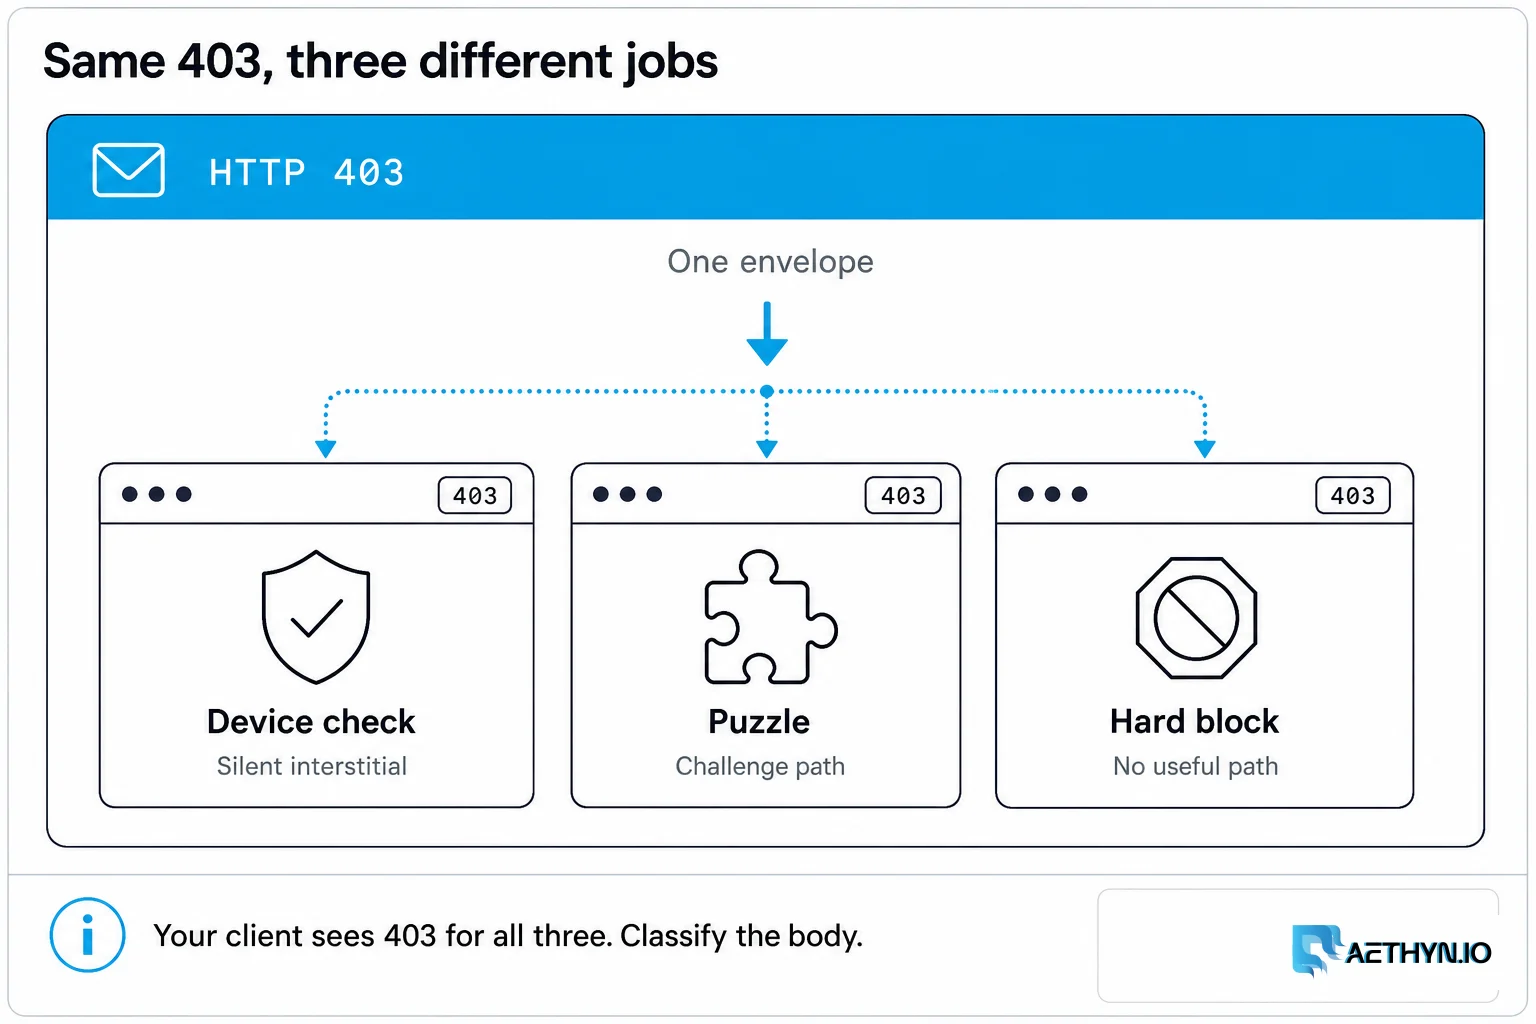
DataDome 403: Same Status, Different Outcomes (Scraping)
DataDome returns HTTP 403 for device check, CAPTCHA, and ban. Learn x-datadome: protected, the datadome cookie, and how to classify bodies before rotating proxies.
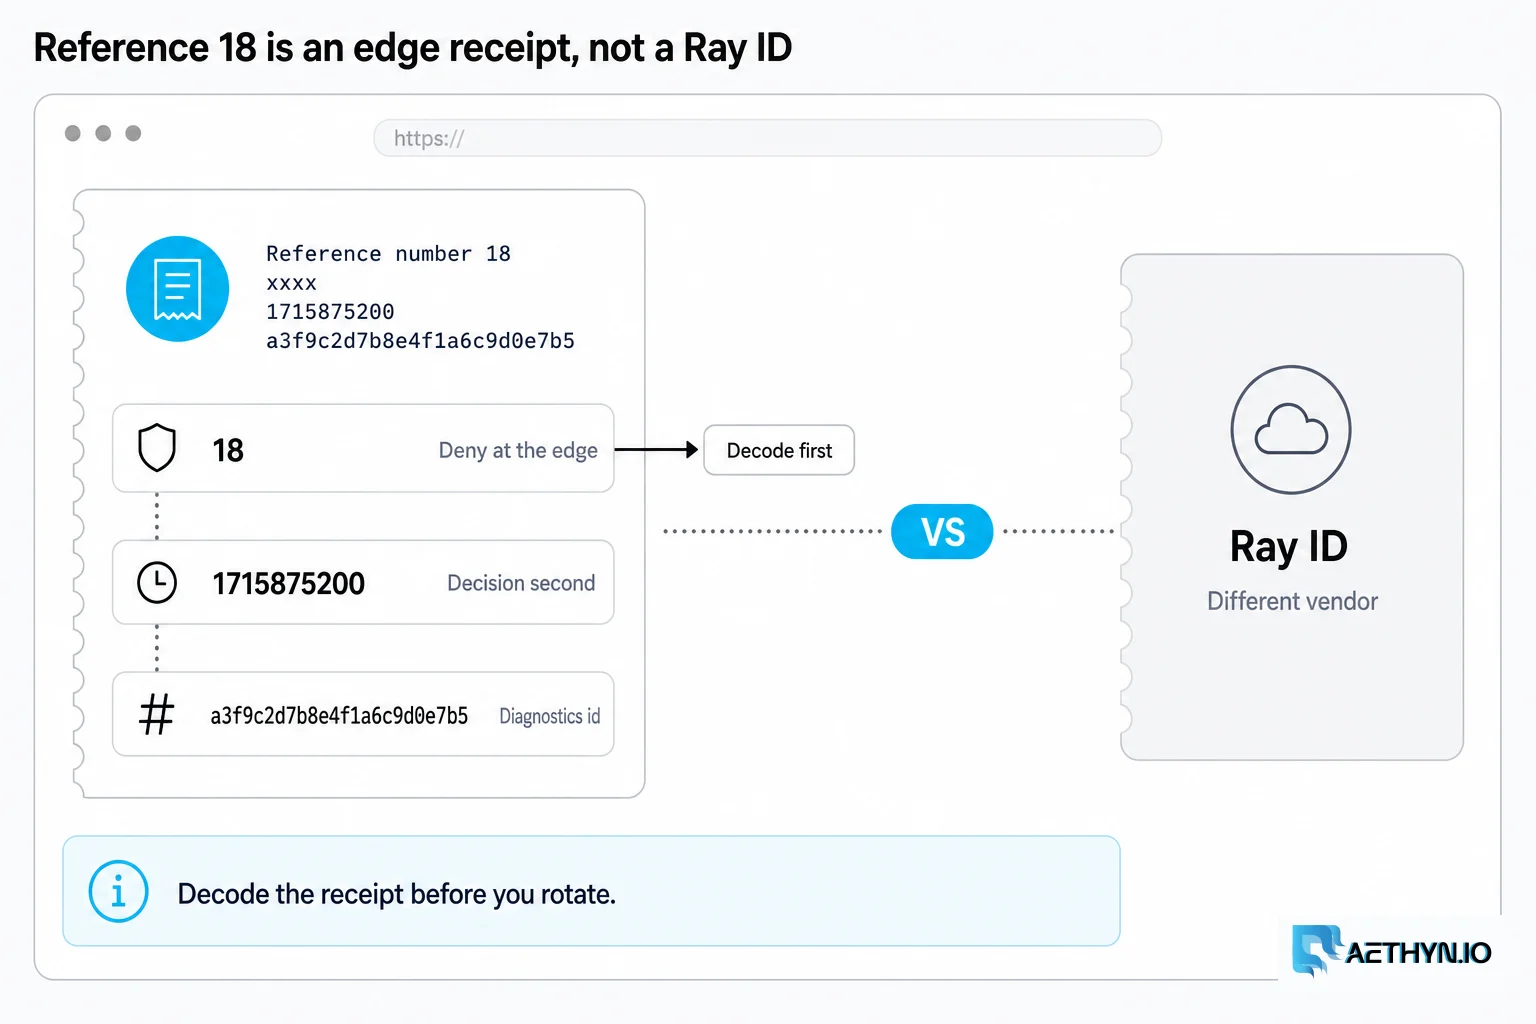
What Is Akamai Reference #18 Access Denied? (Scraping Guide)
Reference #18 means Akamai edge Access Denied — not a random Ray ID. Decode the receipt, separate #9 malformations from bot decisions, and know when residential proxies help.
Classify every navigation before you wait
Wire status + title checks around Playwright, then use Premium 2099 or Elite 5499 only when attribution says the IP layer failed.