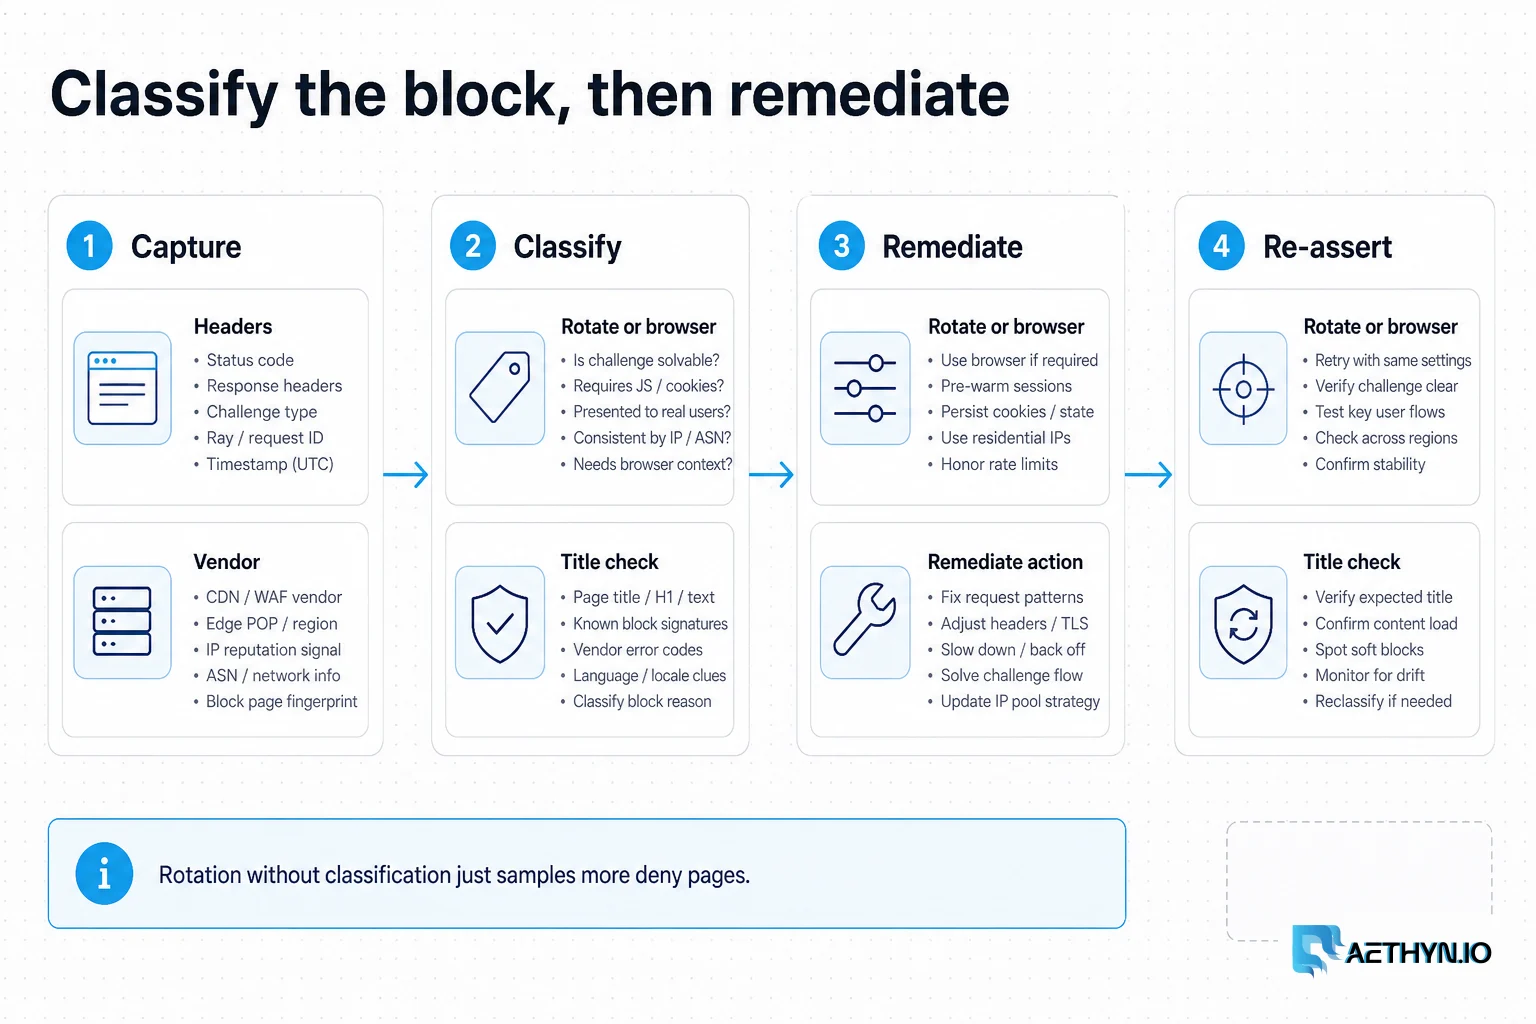
Pipeline stages from request to verified data
Navigate
Capture Response/status (Playwright) or immediate title/URL (Selenium) — never assume throw-on-deny.
Classify
Map status + title + body markers to block vs document vs network failure.
Assert
Require commerce selectors only after classification says the document is real.
Attribute
Send the artifact tuple to the anti-bot hub before changing proxies.
Remediate
IP-shaped → residential; fingerprint/JS → client stack; never retry blindly on silence.
How to build each pipeline stage
- 1
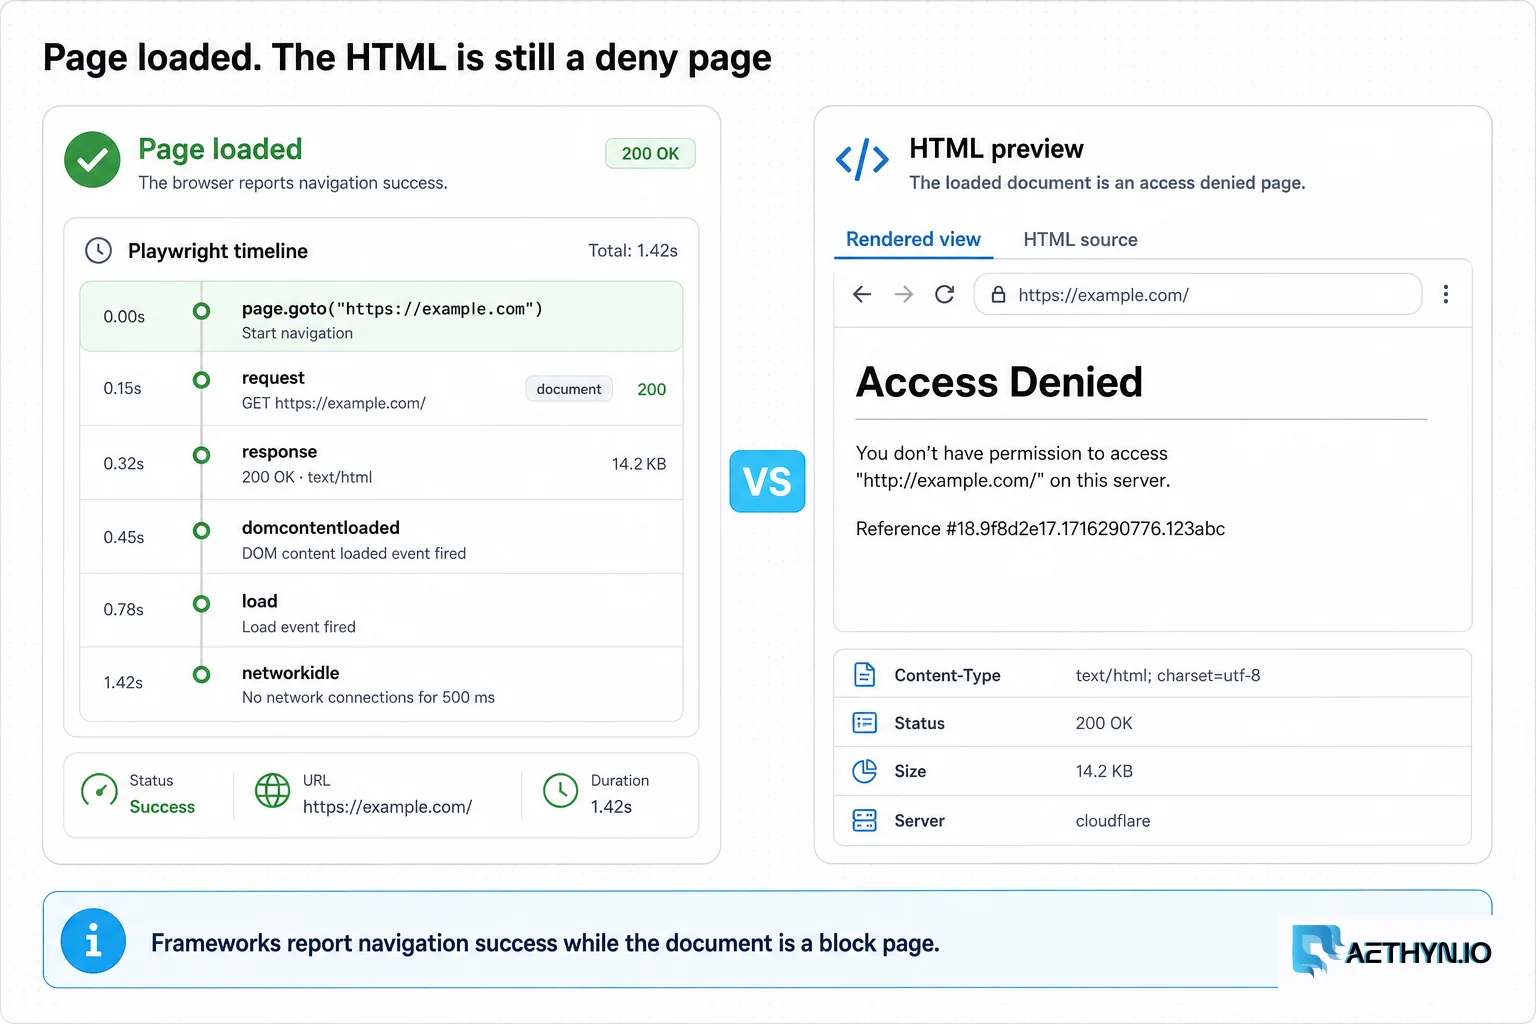
Treat navigation as data, not success
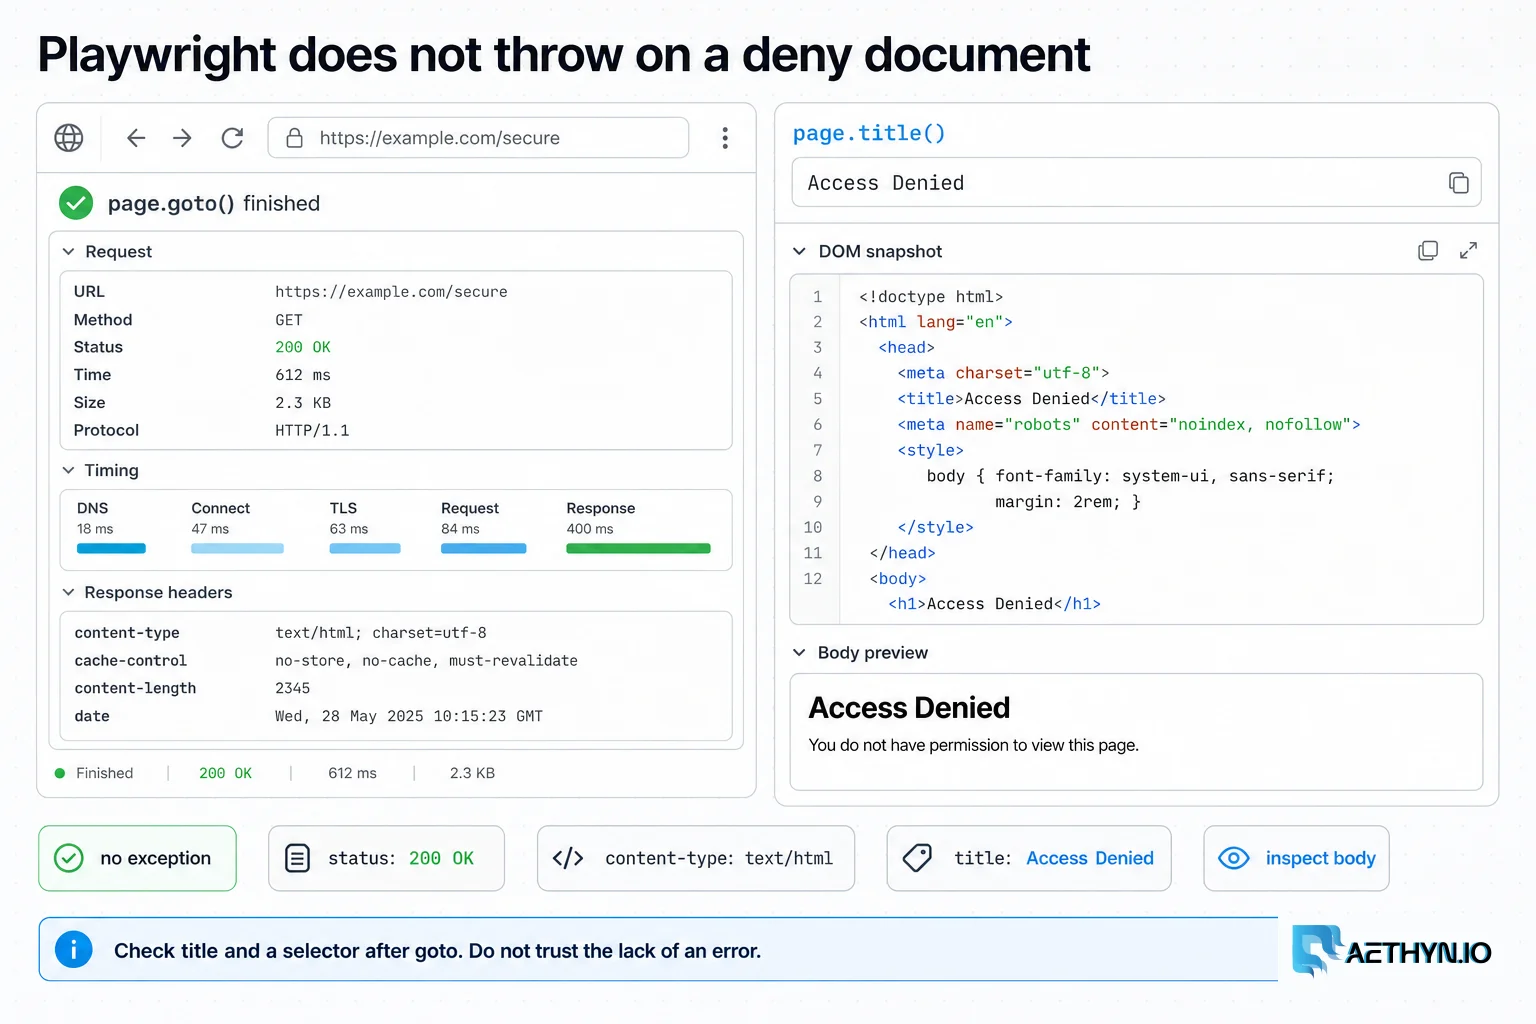
In Playwright, always read the Response from page.goto (or wait_for_response). Log status, final URL, and title before any commerce locator. In Selenium, read driver.title and page_source length immediately after get().
Python (Playwright)from playwright.sync_api import sync_playwright def goto_classified(page, url: str): resp = page.goto(url, wait_until="domcontentloaded", timeout=45_000) status = resp.status if resp else None title = page.title() return {"status": status, "title": title, "url": page.url} # Verified class of behaviour: status 403 → no exception from goto itself. - 2
Build the classify stage before waits
If status >= 400, or title matches Access Denied / Just a Moment / px-captcha patterns, fail closed with a BlockedError. Only then call wait_for_selector on product nodes.
Python (Selenium sketch)from selenium import webdriver def get_classified(driver, url: str): driver.get(url) # raises nothing on HTTP 403 HTML title = driver.title or "" if "access denied" in title.lower(): raise RuntimeError(f"blocked_document title={title!r}") return title - 3
Separate proxy failures from site blocks
A dead proxy yields net::ERR_PROXY_CONNECTION_FAILED quickly in Playwright. A 407 without credentials can hang until the goto timeout with no status — configure proxy username/password first. That hang is not an anti-bot signal.
- 4
Three-way curl outside the browser
When the browser is silent, confirm the wire with plain curl, Chrome-UA curl, and residential curl so you know whether the framework merely hid a normal HTTP deny.
bashURL=https://TARGET/ UA='Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/128.0.0.0 Safari/537.36' echo plain; curl -sS -o /dev/null -w '%{http_code}\n' "$URL" echo ua; curl -sS -o /dev/null -w '%{http_code}\n' -A "$UA" "$URL" echo res; curl -sS -o /dev/null -w '%{http_code}\n' -A "$UA" \ -x 'http://aethyn-XXXXX-country-us:PASSWORD@proxy.aethyn.io:2099' "$URL" - 5
Attribute with the hub, then remediate once
Pass status, Set-Cookie names, and body prefix into /solutions/identify-antibot-blocking-your-scraper. Choose residential vs browser-grade client from that matrix — do not invent a bypass from a TimeoutError string.
What goes wrong when this scraper fails
Engineers search for “why is my locator timing out” when the real event was a block document that the automation API treated as a successful navigation. Under-served queries cluster around Playwright and Selenium because both stacks optimise for “page loaded,” not “page is the product HTML you wanted.”
Challenges that make this hard to automate
- No exception on HTTP deny documents
- Empty TimeoutException messages in Selenium
- Confusing proxy auth hangs with site blocks
- Scrapy ignoring 403 by default looks like “no items”
- Teams rotating IPs while the framework never classified the page
How Aethyn residential proxies help here
Use Aethyn when the pipeline’s Attribute stage says reputation/velocity/geo. Keep credentials in the Playwright proxy object or Selenium options with the published ports.
- Premium HTTP 2099 for routine residential A/B after classification
- Elite HTTP 5499 when Bot Management–class targets are confirmed
- SOCKS5 1099 / 3499 for clients that prefer SOCKS
- Sticky -session-…-lifetime-N when a browser flow must reuse one exit
- Clear 407 vs site-block separation once proxy auth is configured correctly
Common questions about this scraper problem
Does Playwright throw when a site returns HTTP 403?
Does Selenium raise on an Access Denied page?
Why did Playwright hang 30s with a proxy?
Where do residential proxies fit in this pipeline?
Is Scrapy silent too?
Does this guide teach CAPTCHA solving?
Best practices that keep scrapers reliable
- Log status + title on every navigation
- Fail closed on deny titles before commerce waits
- Configure proxy auth explicitly in Playwright
- Keep a non-browser three-way curl in the incident kit
- Public-data scope only — no CAPTCHA solve automation
Common mistakes that burn proxy budget
- Reading TimeoutError as “site slow”
- Ignoring response.status after goto
- Assuming Selenium throws on HTTP 403
- Rotating IPs before classification
- Equating proxy 407 hangs with vendor blocks